Publications
Papers and preprints
Publications and preprints by Wang Chen on long-video understanding, multimodal reasoning, and generative vision.
01
Conference papers
CVPR 2026
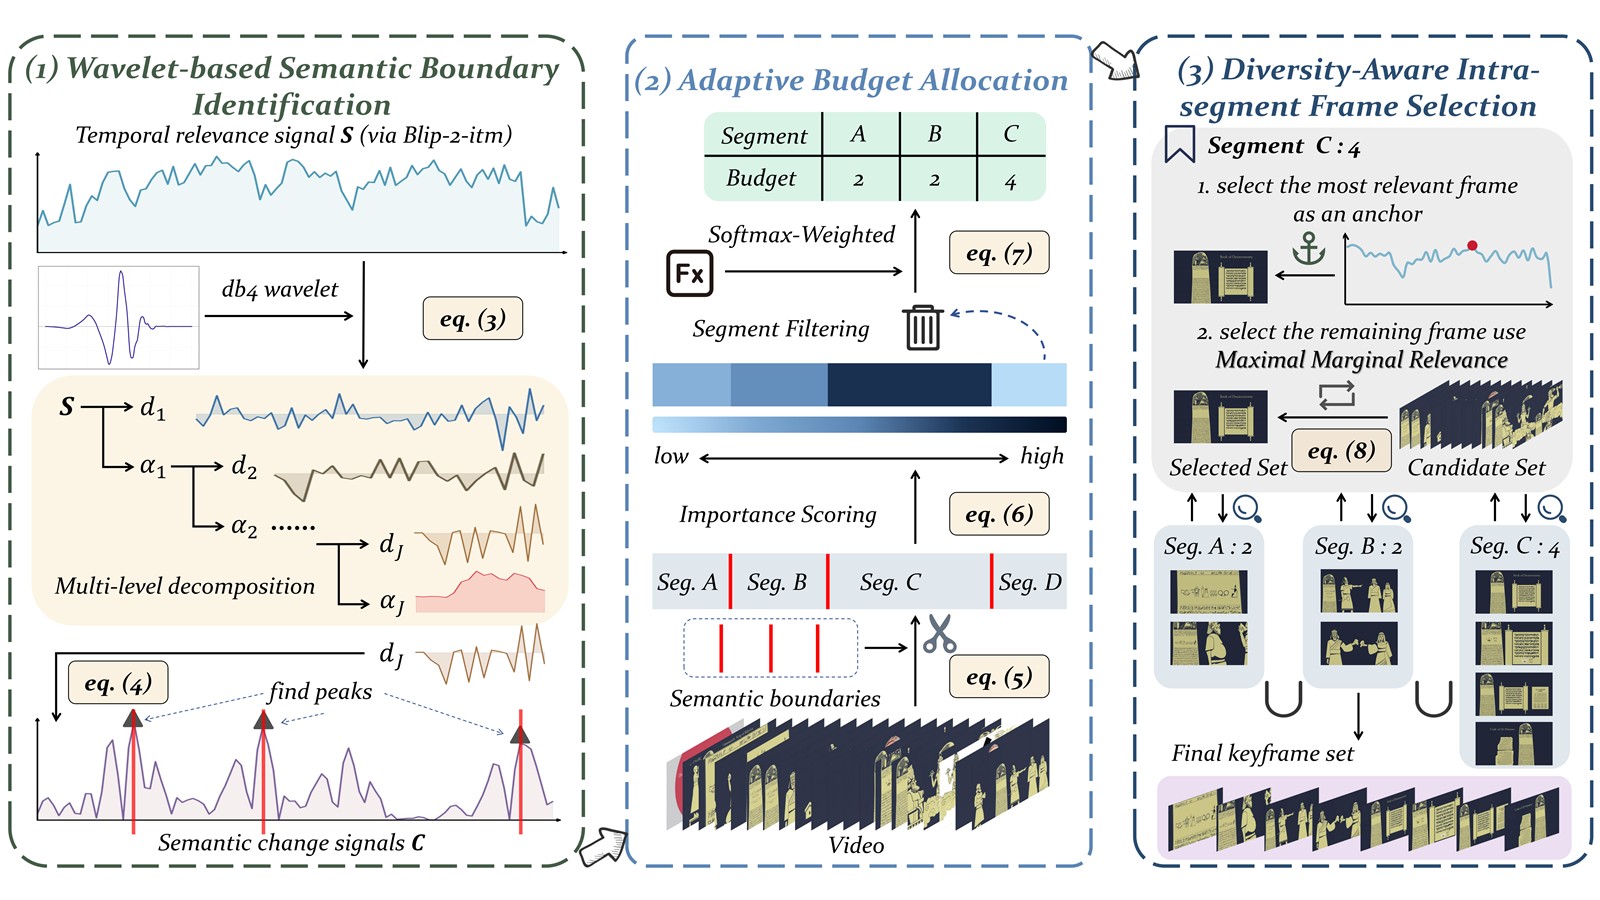
Wavelet-based Frame Selection by Detecting Semantic Boundary for Long Video Understanding
Wang Chen, Yuhui Zeng, Yongdong Luo, Tianyu Xie, Luojun Lin, Jiayi Ji, Yan Zhang, Xiawu Zheng
Detects semantic boundaries from a noisy query-frame relevance signal, then allocates frame budgets by segment importance. The training-free method improves VideoMME, MLVU, and LongVideoBench by 5.5, 9.5, and 6.2 points.
AAAI 2026 · Equal contribution
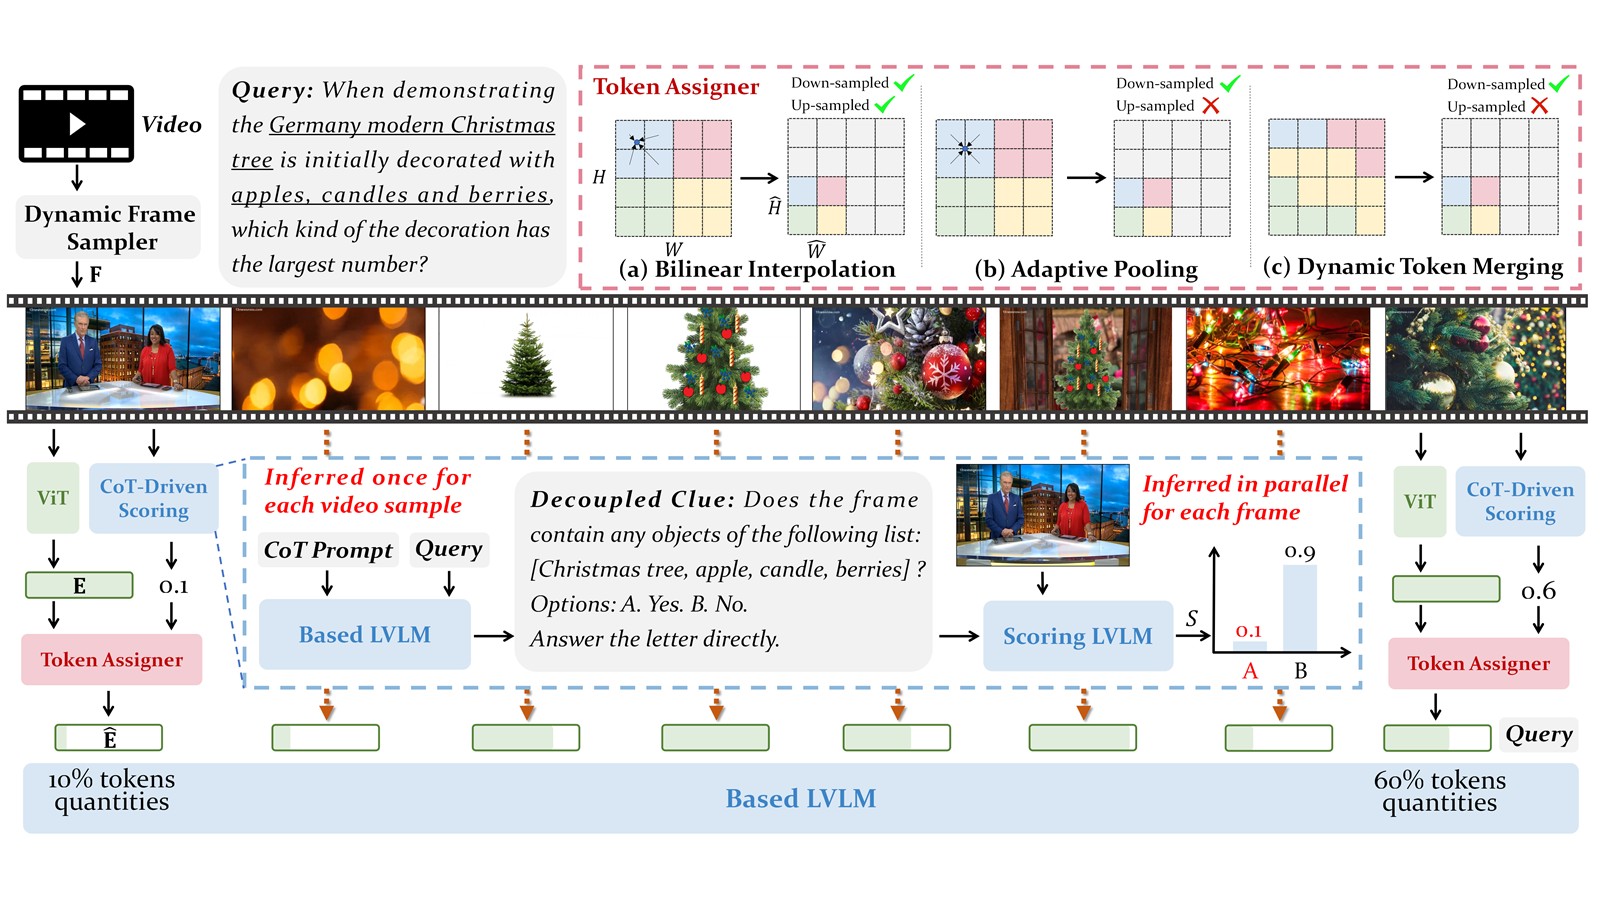
QuoTA: Query-oriented Token Assignment via CoT Query Decouple for Long Video Comprehension
Yongdong Luo*, Wang Chen*, Weizhong Huang, Shukang Yin, Haojia Lin, Jinfa Huang, Chaoyou Fu, Jiayi Ji, Xiawu Zheng, Jiebo Luo
Allocates visual tokens to frames before cross-modal interaction. CoT turns a complex query into scorable clues, improving six video benchmarks by 3.2 points on average under the same token budget.
ICASSP 2023 · Equal contribution
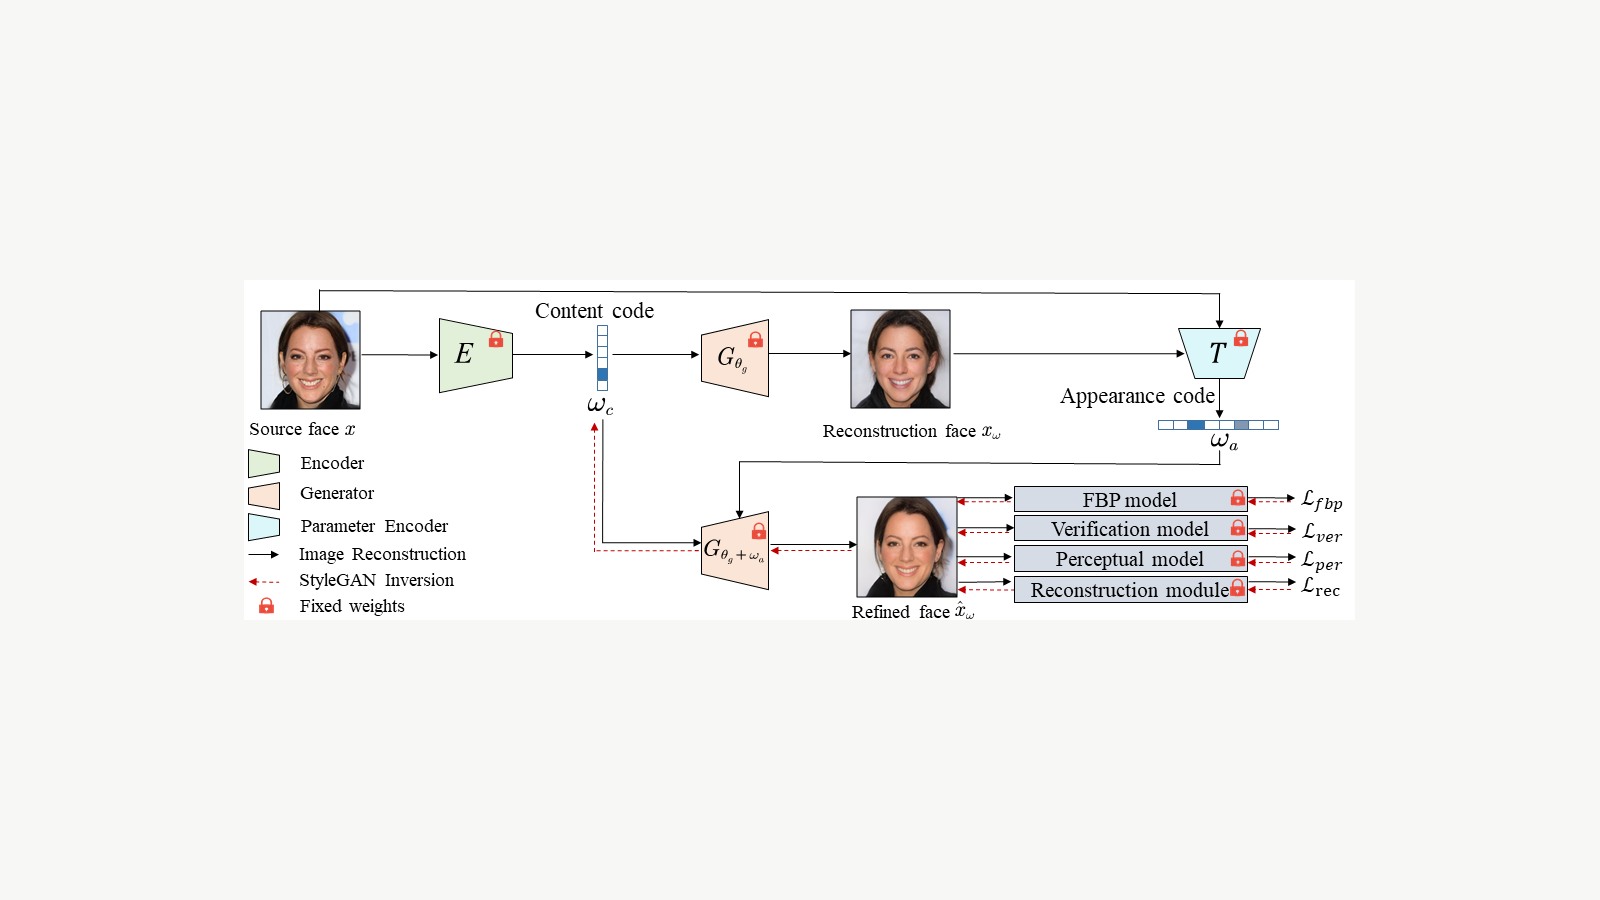
Customized Automatic Face Beautification
Wang Chen*, Peizhen Chen*, Weijie Chen, Luojun Lin
Uses facial-aesthetics-guided StyleGAN inversion to match a user-specified target score while preserving identity information.
ICML 2026
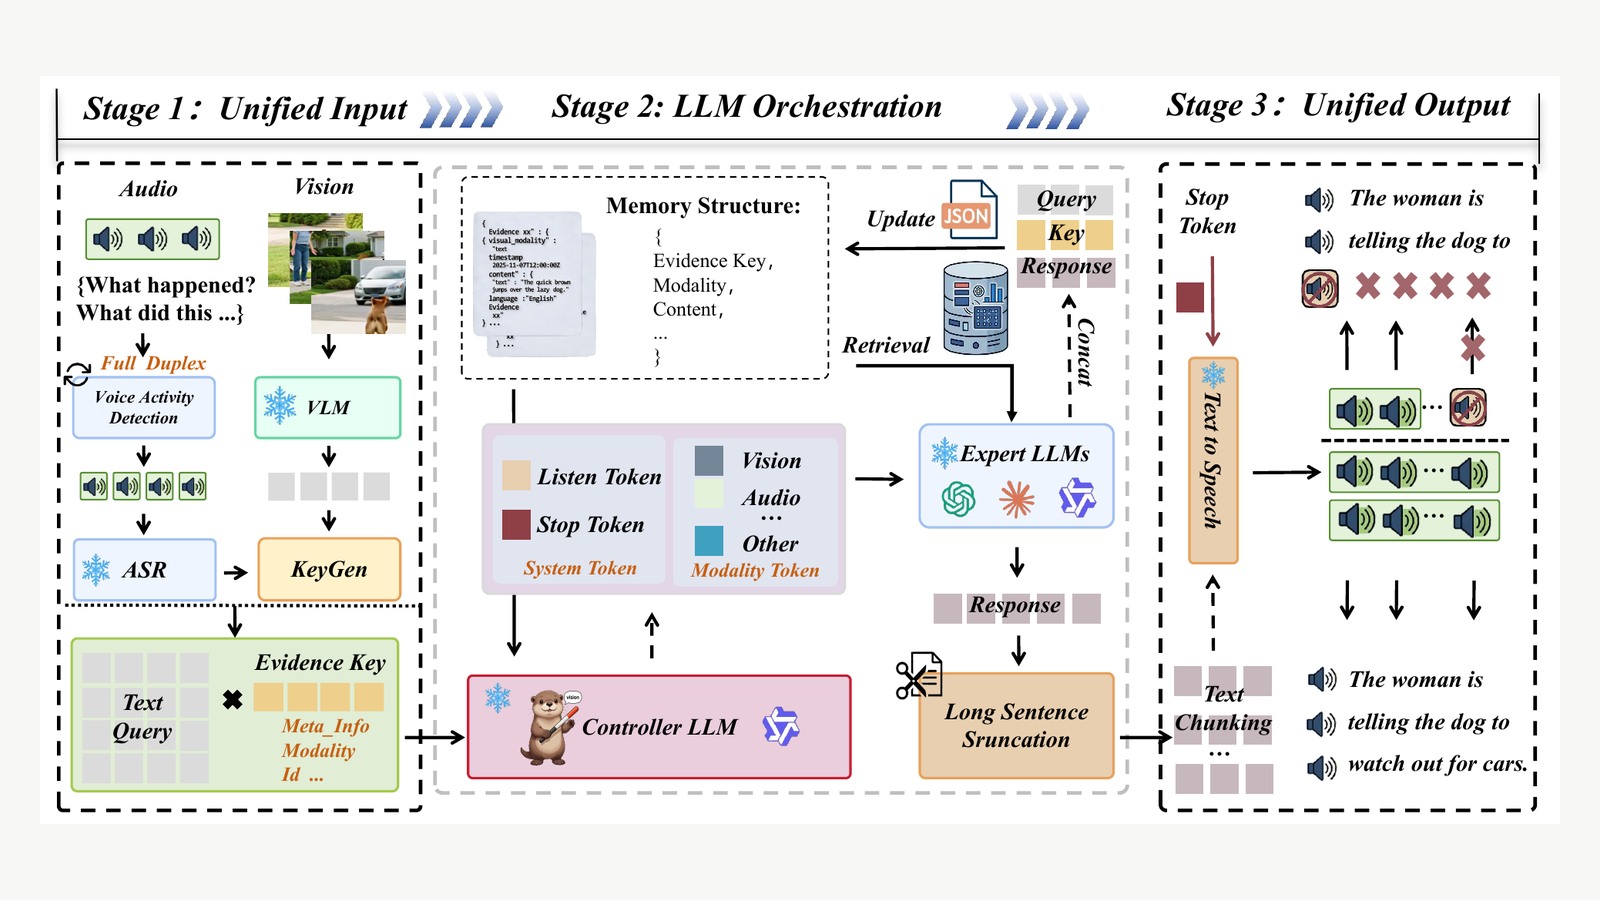
Training-Free Multimodal Large Language Model Orchestration
Tianyu Xie, Yuexiao Ma, Yuhang Wu, Wang Chen, Jiayi Ji, Tat-Seng Chua, Xiawu Zheng, Rongrong Ji
Combines off-the-shelf modality experts without additional training through an LLM controller, textualized cross-modal memory, and a full-duplex interaction layer.
02
Preprints
arXiv preprint · Equal contribution
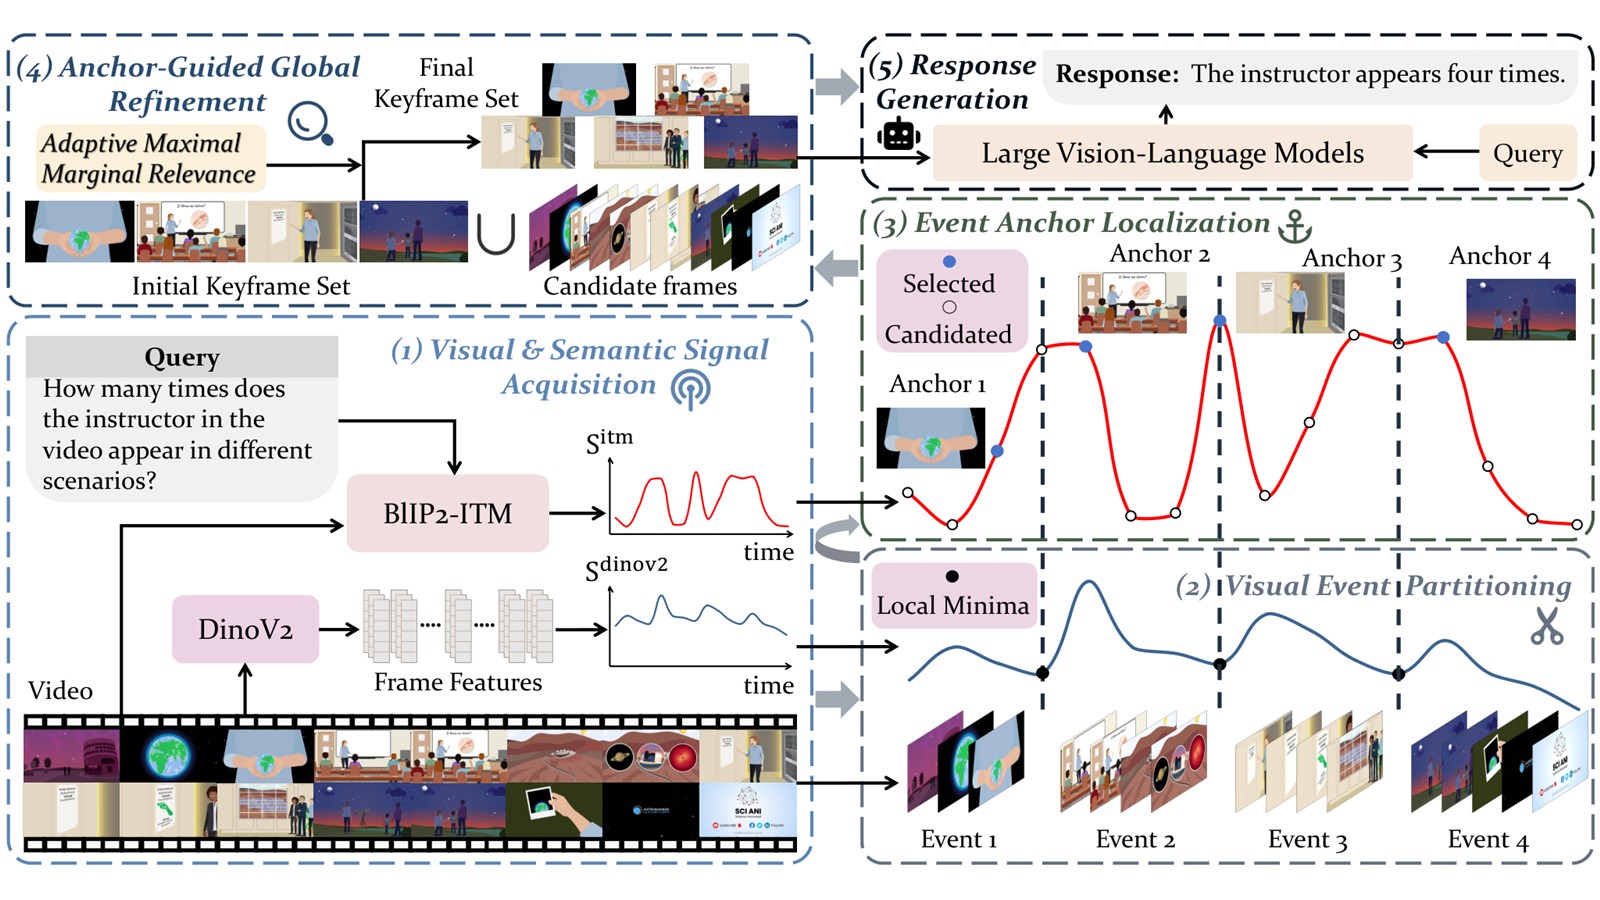
Event-Anchored Frame Selection for Effective Long-Video Understanding
Wang Chen*, Yongdong Luo*, Yuhui Zeng, Luojun Lin, Tianyu Xie, Fei Chao, Rongrong Ji, Xiawu Zheng
Partitions video into coherent events, localizes a query-relevant anchor in each event, and applies adaptive MMR for global refinement across coverage, relevance, and diversity.
SSRN preprint
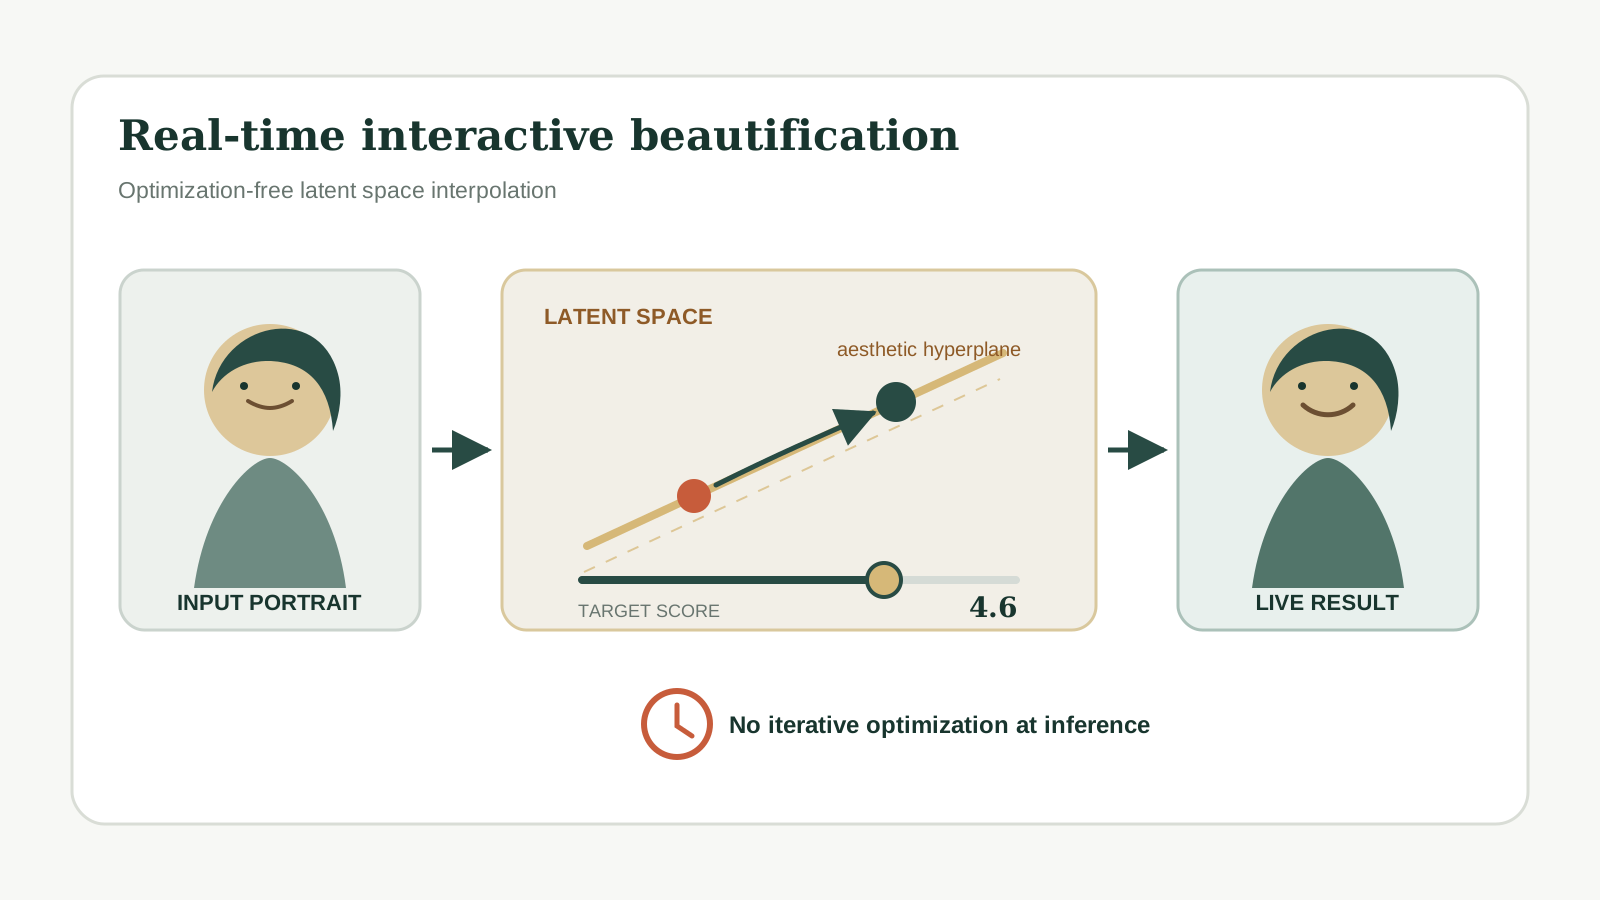
Real-Time Interactive Face Beautification
Luojun Lin, Wang Chen, Peizhen Chen, Xiawu Zheng, Lianwen Jin
Constructs an aesthetics hyperplane and interpolates directly in latent space for real-time, target-score-controlled editing with identity preservation.
arXiv preprint
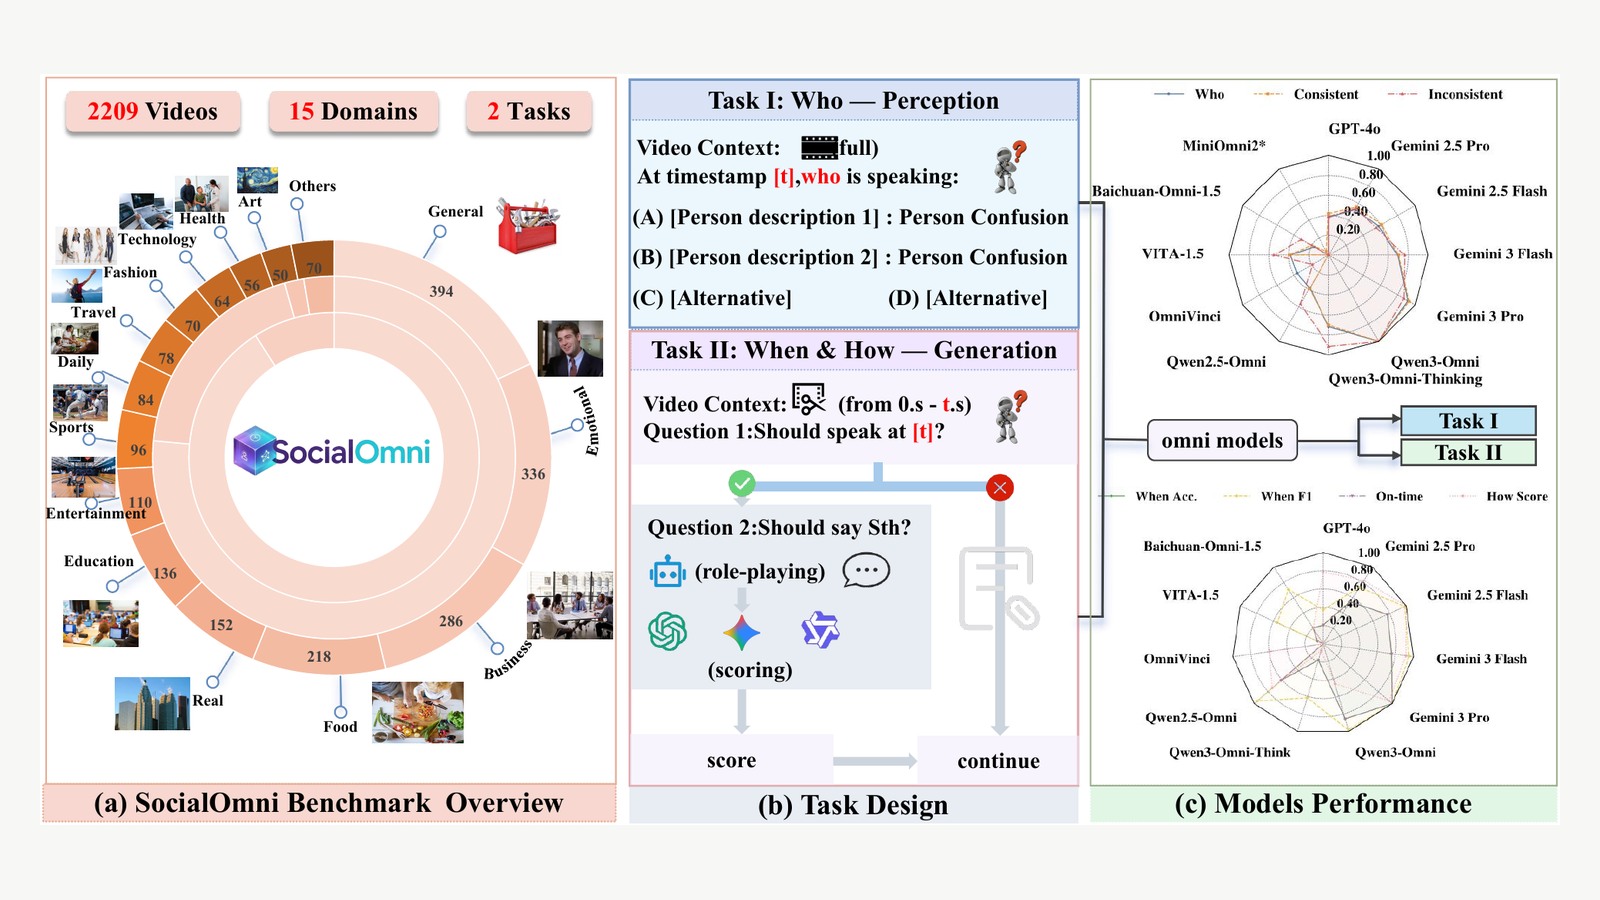
SocialOmni: Benchmarking Audio-Visual Social Interactivity in Omni Models
Tianyu Xie, Jinfa Huang, Yuexiao Ma, Rongfang Luo, Yan Yang, Wang Chen, Yuhui Zeng, Yixuan Zou, Qingchuan Ma, Zhiqiang Lu, Ruize Fang, Xiawu Zheng, Jiebo Luo, Rongrong Ji
Evaluates audio-visual social interaction through speaker perception, interruption timing, and response behavior, exposing gaps between perception accuracy and interaction quality.
arXiv preprint
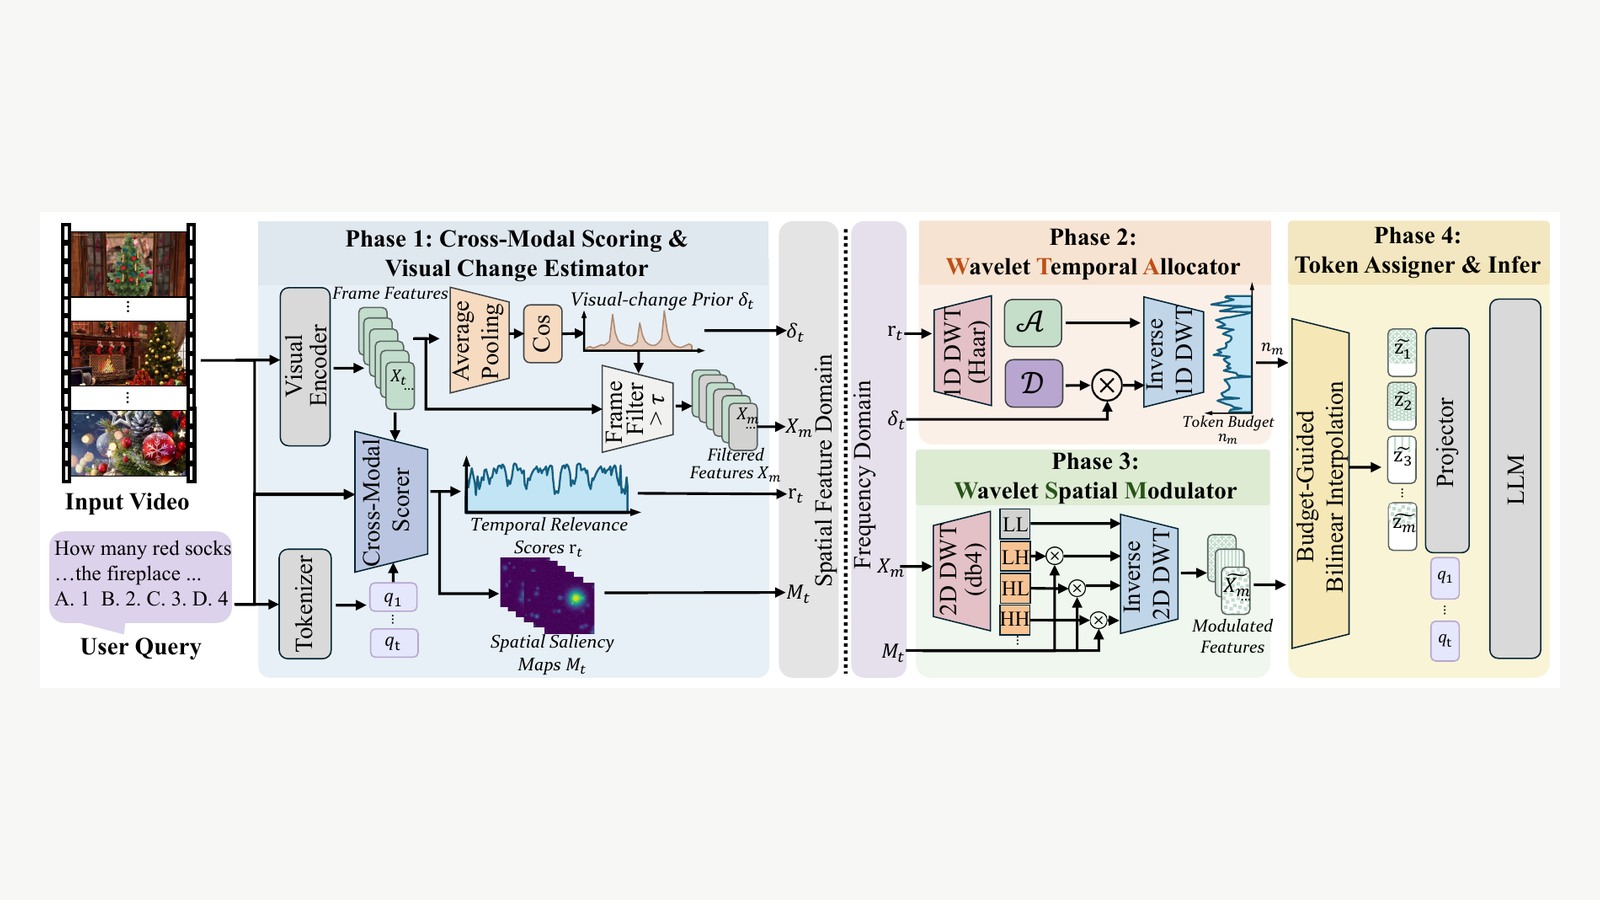
WaveZip: Wavelet-Driven Space-Time Decoupling for Video Token Condensation
Yuhui Zeng, Wang Chen, Jinfa Huang, Tianyu Xie, Yongdong Luo, Jiayi Ji, Xiawu Zheng, Jiebo Luo
Uses spatial-temporal decoupled wavelet analysis to allocate frame-level budgets and compress spatial tokens while preserving performance at high compression ratios.
arXiv preprint
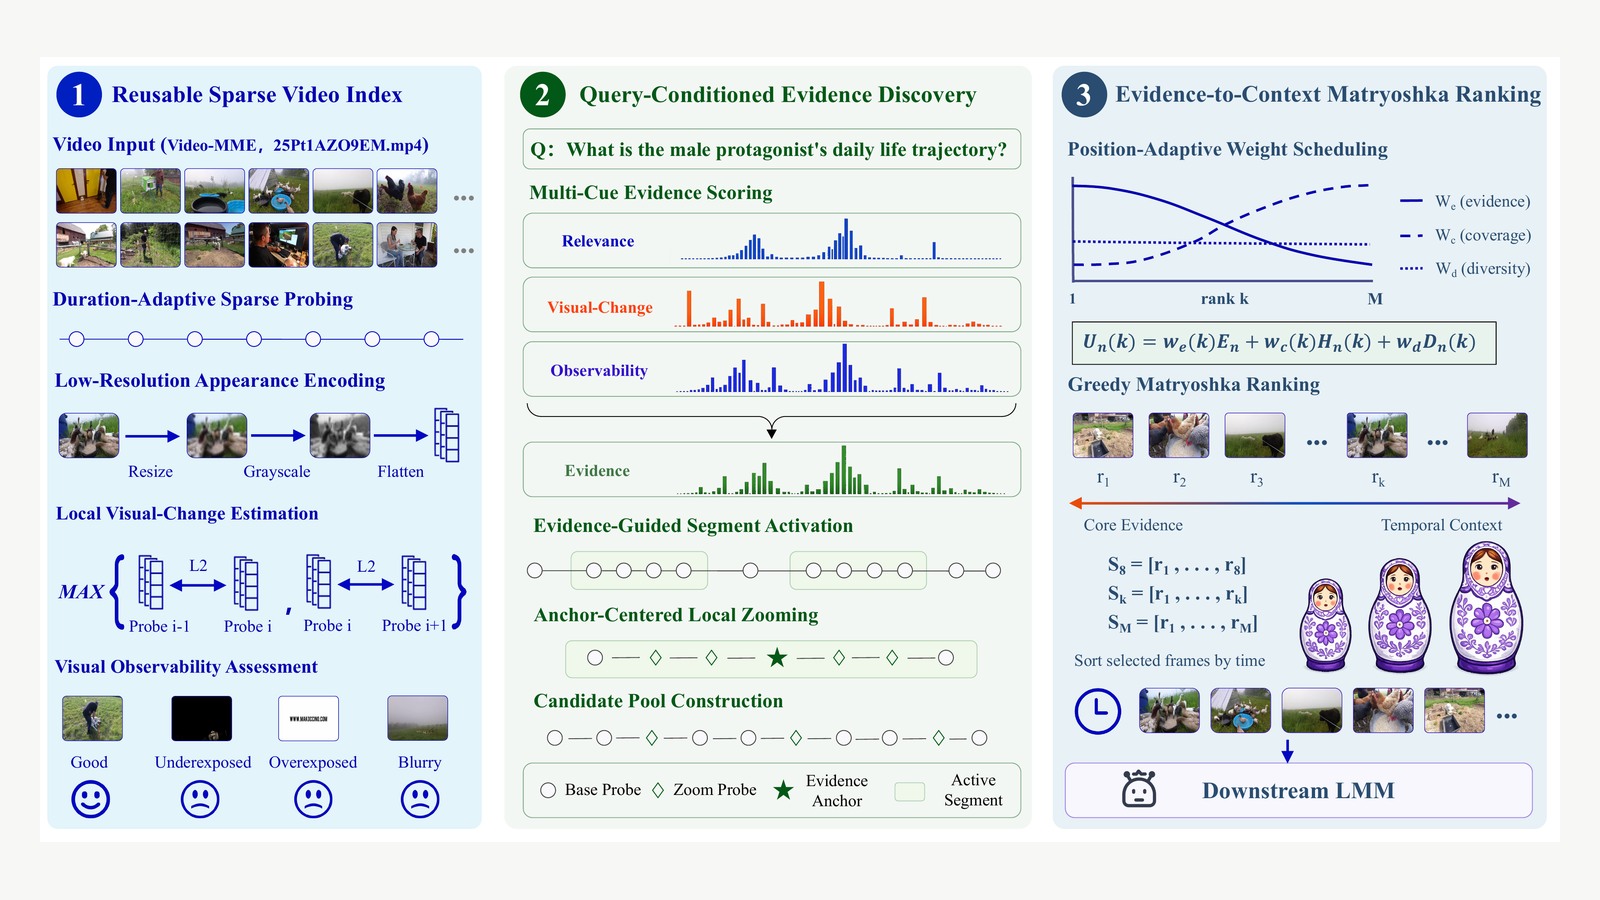
One Ranking, Any Budget: Matryoshka Evidence-to-Context Frame Selection for Long-Video Understanding
Wang Chen, Yu Chen, Xiang Wang, Shuai Li, Jinfa Huang, Xiawu Zheng
Produces a single frame priority ranking that can be truncated at any budget, progressively expanding from local evidence to temporal context while avoiding repeated selection.
Author order and publication status are checked against the paper pages. * denotes equal contribution. Preprints are not labeled with withdrawn or pending submission venues.
 2026